Microsoft 365 outage exposes the dependency stack beneath enterprise AI
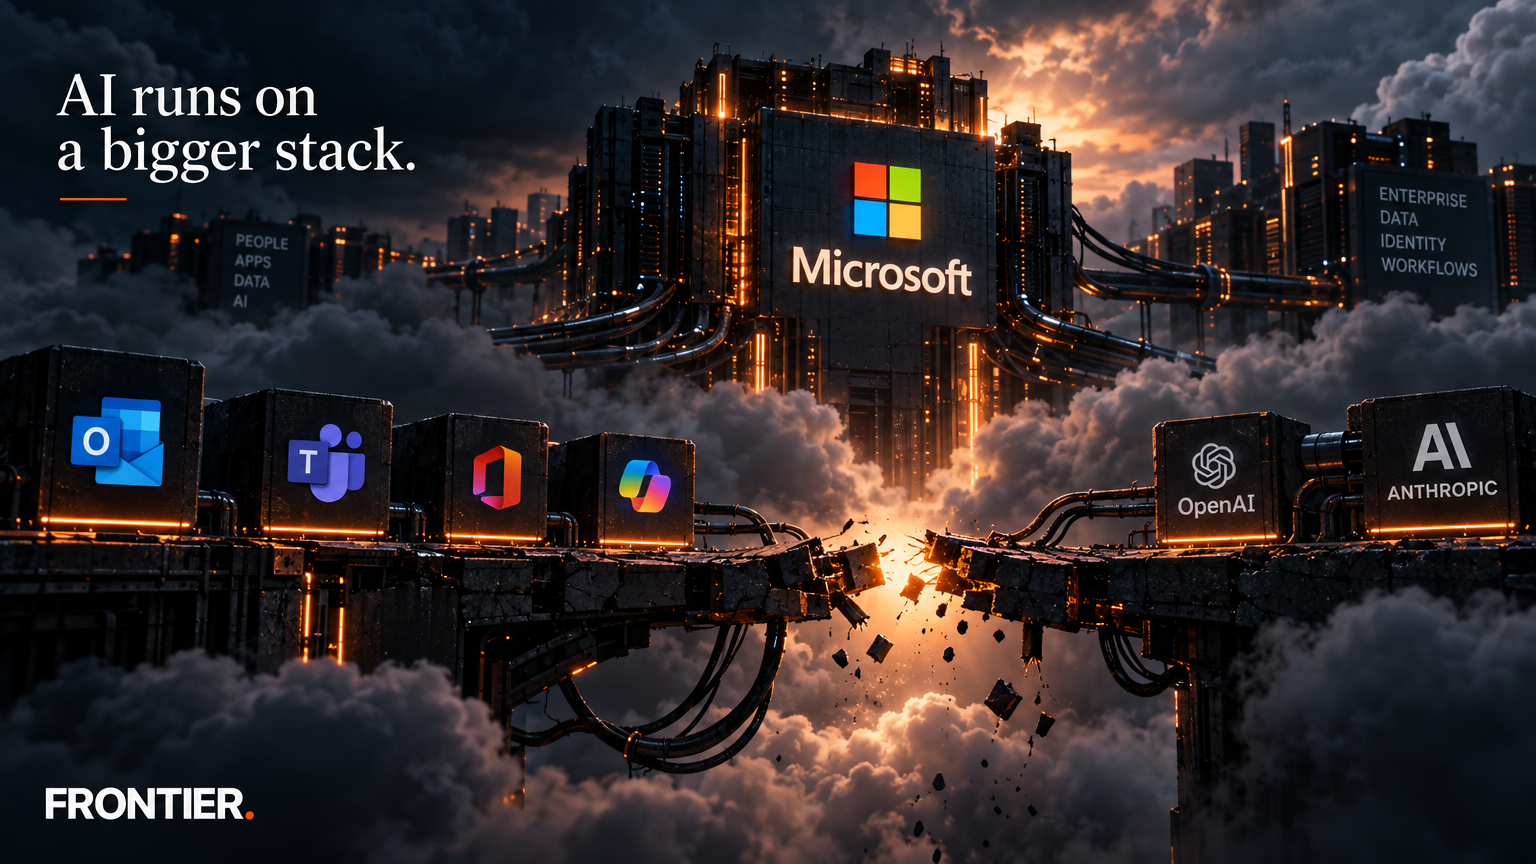
Microsoft’s November 12, 2026 service degradation disrupted Outlook, Microsoft 365 Copilot and Exchange-dependent Teams features around the world while impairing Microsoft 365 connectors used by OpenAI and Anthropic—a sign that enterprise AI resilience now depends on the full chain connecting models, applications and corporate data.
Take the argument with you.
Read the publication-ready report. Generated from the canonical News article.
What changed
Microsoft recorded incident MO1550821 as beginning at 18:26:10 UTC on November 12, 2026, classifying it as a Microsoft 365 suite service degradation rather than a failure isolated to one application.1 The company identified impact across Exchange Online, Microsoft Teams, SharePoint Online, Microsoft 365 Copilot and Microsoft Defender XDR, with later updates documenting additional feature-level effects across Microsoft 365.1
The disruption is substantial, but its boundaries are important to understand. Microsoft said Microsoft 365 Copilot users could be unable to load Copilot Chat, receive responses or access work data such as email, calendars and files.1 Outlook and Exchange were central to the incident. Associated Press reported nearly 130,000 Outlook-related Downdetector reports shortly after 1 p.m. Eastern, while Reuters reported more than 97,000 Outlook reports, more than 38,000 Microsoft 365 reports and approximately 4,500 Teams reports at the specified observation times.23 Reuters cautioned that those user-submitted reports did not represent a verified count of affected users, but reports have been global and widespread.3
Significantly, Teams was not uniformly unavailable. Microsoft’s disclosure said most core calling, meeting, group-chat and channel-message functions were not affected, while Exchange-dependent scenarios—including calendar, event, contact and some channel-management functions—could fail.1 That distinction changes the interpretation of the event: one product could appear operational at the application level while important workflows inside it were degraded because they depended on another service.
The incident also crossed vendor boundaries through AI connectors. OpenAI reported elevated errors affecting its Microsoft 365 connector, including potentially broken new connections and tools that did not work as expected.4 Anthropic reported failures involving mail, SharePoint, Teams chat and calendar requests through its Microsoft 365 connector, subsequently attributing the problem to the Microsoft 365 incident.5 The primary disclosures establish connector-level disruption; they do not establish a general outage of OpenAI’s or Anthropic’s core inference services.
Microsoft’s preliminary investigation said a secure-connection process on affected servers was becoming overwhelmed and that the start of impact correlated with a recent network configuration change.1 BleepingComputer separately reported Microsoft’s finding that unexpectedly unavailable servers shifted load onto remaining infrastructure.6 These were preliminary explanations, not a completed root-cause determination. Microsoft also stated on November 13 that it was not aware of malicious activity causing the incident and said a post-incident report would follow mitigation, but cyber interference or attack(s) cannot yet be ruled out.1
Why it matters
The conventional CIO and CISO availability model tend to evaluate products in separate columns: collaboration, email, cloud infrastructure, security and AI. That model is increasingly incomplete. AI assistants are becoming an access layer over email, calendars, files and collaboration systems. Their operational value therefore depends not only on whether a model endpoint responds, but also on whether identity, connectors, permissions, source applications and data-retrieval paths remain usable.
The Microsoft incident demonstrates the difference between model availability and task availability. An AI service can remain capable of generating responses while becoming unable to retrieve the enterprise context required for a useful answer. OpenAI’s and Anthropic’s status disclosures showed problems specifically with their Microsoft 365 connectors, while Microsoft documented Copilot failures involving access to email, calendars and files.451 The defensible conclusion is not that multiple core AI platforms failed simultaneously. It is that a shared enterprise-data dependency impaired several AI experiences at once.
That changes the CIO cloud decision framework in three important ways. First, resilience must be assessed at the workflow level rather than solely through vendor-wide uptime. A status dashboard may show that Teams meetings or an AI model remain available even when a workflow such as preparing for a meeting, retrieving correspondence or acting on a calendar request is broken. Microsoft’s own feature-level disclosure illustrates this fragmentation: core Teams communications largely remained functional while Exchange-dependent features could fail.1
Second, apparent AI diversification may not provide operational diversification. Deploying assistants from multiple vendors can improve commercial leverage or offer different model capabilities, but it does not create resilience when those assistants retrieve the same data through the same cloud application and connector path. The OpenAI and Anthropic incidents are evidence of this shared dependency at the connector layer.45 It is an analytical inference—not a reported vendor conclusion—that enterprises treating the two products as independent continuity options could still encounter correlated workflow failures.
Third, recovery objectives must include context and action, not just interface access. A CIO may be able to report that an assistant is online while employees cannot obtain current email, calendar or file context. For a business process, that can be equivalent to an outage even when the model is technically reachable. Procurement scorecards built around model uptime, aggregate cloud availability or application-level service commitments will miss this gap unless they measure the complete path from user request to authorized enterprise data.
The practical shift is from asking, “Is the AI platform available?” to asking, “Which business outcomes remain executable when any component in the AI dependency chain is degraded?” That requires dependency mapping, correlated-failure testing and explicit degraded-mode procedures. It also requires incident communications that distinguish model failure, connector failure, source-system failure and feature-level degradation. Without that precision, executives may overestimate both the scope of an incident and the protection offered by a second AI vendor.
Frontier take
The dependency graph—not the AI product—is now the correct unit of enterprise resilience. In addition, the extended outage, which is still not fully resolved and remains poorly explained, will significantly damage Microsoft’s cloud reliable narrative going forward.
These assertions follow from the structure of the incident. Microsoft 365 Copilot’s access to work data was impaired within Microsoft’s environment, while OpenAI and Anthropic separately disclosed Microsoft 365 connector problems.145 The common operational denominator was access to Microsoft 365 services and data, not evidence of a simultaneous failure across the vendors’ underlying models. The outage therefore exposed a control point that conventional AI evaluations often obscure: the route between an assistant and the systems of record it is expected to understand or act upon.
The key lesson, which has been slowly but steadily arriving, is that CIOs must now treat enterprise AI as a composite service. That composite includes the model, orchestration layer, connector, identity and authorization controls, source application, data service and any workflow used to execute an action. Each component can remain nominally available while the composite task fails. The documented split inside Teams—core communications functioning while Exchange-dependent capabilities were disrupted—shows why product-level labels are too coarse.1
This does not mean every enterprise should replicate every data source or build a second integration path. That would be an architectural choice requiring its own cost, security and consistency analysis. It does mean that leaders should know where shared dependencies defeat the resilience assumptions behind a portfolio. If two assistants rely on one connector family, one identity path and one cloud suite, they may offer model diversity without meaningful continuity for data-grounded work.
The same logic should shape governance. Security review normally asks which data an assistant can reach; resilience review must ask what happens when that reach disappears or becomes partial. A safe degraded mode may restrict the assistant to general reasoning, show the age and origin of available context, prevent actions based on stale records, and direct users to a manual workflow. The appropriate response will vary by process, but it should be designed before an incident rather than improvised during one.
Microsoft had not published a final root cause in the supplied disclosures at the time of this writing, so it would be premature to turn the preliminary network correlation into a definitive architectural judgment.1 The strategic lesson does not require that conclusion. The verified impact already shows that cloud-application degradation can propagate into first-party and third-party AI experiences through shared data and connector dependencies. AI resilience is therefore not an additional uptime percentage to collect from a model vendor. It is a property of the end-to-end enterprise workflow.
Three moves for CIOs
-
— Build a new cross-cloud, task-level AI dependency register Select the highest-consequence AI-assisted workflows and map each one from user request to model, orchestration service, connector, identity path, source application, data store and downstream action. Assign an owner to every dependency and record which ostensibly different assistants share the same path. Validate the map with architecture telemetry and incident evidence rather than relying only on vendor diagrams.
- Decision trigger: Require the register before approving any major workflow (AI or otherwise) that reads corporate email, calendars, files or collaboration data, or when two candidate assistants depend on the same system of record or connector family.
- Why now: Microsoft 365 degradation affected Microsoft’s own Copilot data access while OpenAI and Anthropic reported problems with their Microsoft 365 connectors.145 That pattern shows why counting AI vendors does not reveal correlated exposure. A task-level register gives the CIO a basis for deciding where redundancy is real, where it is cosmetic and where a manual fallback is the more rational investment.
-
— Contract for workflow observability, not just platform uptime Add procurement and renewal requirements for component-level incident signals covering model access, connector health, authentication, source-data retrieval and action execution. Require vendors — yes, even Micrxosoft — to distinguish complete outages from partial feature degradation and to expose enough status information for the enterprise to determine which business tasks remain safe and usable. This may require customers to band together to achieve but extended downtimes are major business disruptors.
- Decision trigger: Escalate contractual requirements when a vendor offers only aggregate availability metrics, when a connector is excluded from the core service commitment, or when a critical workflow can fail while the primary product status remains operational.
- Why now: The incident produced materially different conditions across Outlook, Copilot, Teams features and third-party connectors.14 Microsoft said core Teams calling, meetings and messaging largely remained available even as Exchange-dependent functions failed.1 Aggregate uptime would not adequately describe that operational state, so CIOs need telemetry and obligations aligned with the tasks employees actually perform.
-
— Create a context-loss mode for cloud/AI-assisted work Design and test a degraded mode that detects unavailable or stale enterprise context, tells users exactly which sources cannot be reached, blocks high-consequence actions that require current records and routes work to an approved manual process. Exercise this mode with a scenario in which the model remains reachable but email, calendar, file or collaboration connectors fail.
- Decision trigger: Activate the mode when connector errors cross an enterprise-defined threshold, source data cannot be timestamped or verified, or an assistant cannot confirm access to a required system of record.
- Why now: Microsoft reported that Copilot users could lose access to responses or work data, while OpenAI and Anthropic documented Microsoft 365 connector failures rather than broad core-model outages.145 That is precisely the failure state conventional disaster-recovery exercises can overlook: the assistant is present, but its enterprise context is absent. Testing context loss now converts a hidden dependency into an explicit operating condition.
Sources
- Microsoft public service health status 7
- University of Pennsylvania archive of Microsoft Service Health incident MO1550821 1
- OpenAI Status: Elevated errors affecting the Microsoft 365 connector 4
- Anthropic Status: Elevated errors affecting the Microsoft 365 connector 5
- Associated Press: Widespread outage hits Microsoft apps 2
- Reuters report syndicated by Investing.com 3
- BleepingComputer: Microsoft 365 outage disrupts Outlook, Teams and Copilot 6
[^microsoft-incident-archive][^ap-report][^reuters-report][^openai-status][^anthropic-status][^bleepingcomputer-report][^microsoft-public-status]